For AI labs
Codebases
Licensed private codebases with full git history: the zip layout, the pull request record, how the history is cleaned, pricing, and delivery.
Each codebase is a private production repository, licensed directly from the team that built it and delivered with its full git history and pull request record after secrets and personal data are removed.
From license to delivery
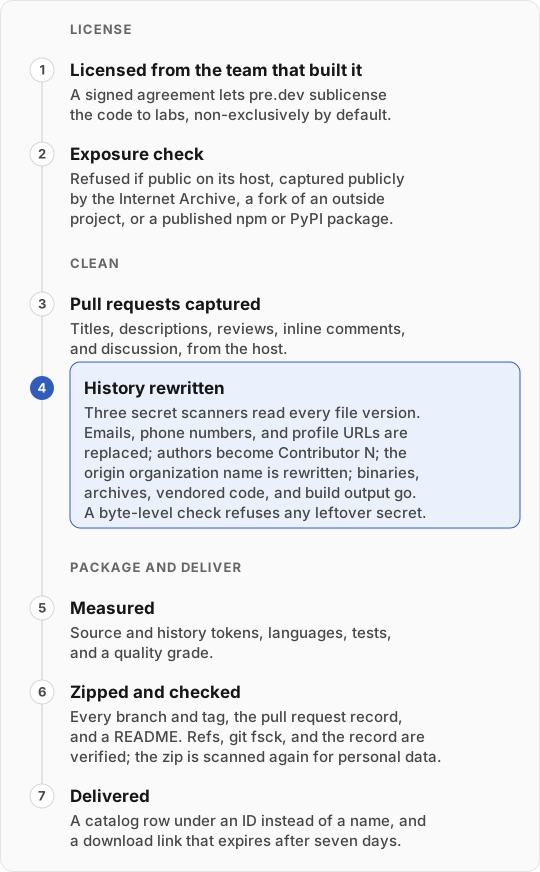
- Licensed from the team that built it, under a signed agreement that lets pre.dev sublicense the code to labs.
- Exposure check. Public, archived, forked, and published code is refused. See exposure check.
- Pull requests captured from the host: titles, descriptions, reviews, inline comments, and discussion.
- History rewritten to remove secrets and personal data. See how the history is cleaned.
- Measured: source and history tokens, languages, tests, and a quality grade.
- Zipped and checked against the delivery checks.
- Delivered as a catalog row and a download link.
What you receive
One zip per repository, named by its catalog ID (PD- and eight hex characters). The zip, its folder, and its README name the repository by that ID only.
PD-XXXXXXXX.zip
└── PD-XXXXXXXX/
    ├── repo/                       the repository with its .git: every branch and tag
    ├── pull_requests.json          the pull request record
    ├── pull_requests.github.json   the same record in the shape of GitHub's REST API
    ├── README.md                   provenance, contents, and how to rebuild a pull request as a task
    └── DATA_CARD.md                the measured facts, on one page
New and rebuilt zips carry DATA_CARD.md. repo/ opens without a clone step. It has no origin remote: every branch is a local branch, so git branch and git log --all see the whole repository. The working tree starts on the host’s default branch.
The pull request record
pull_requests.json is an array with one entry per pull request:
| Field | Meaning |
|---|---|
number, title, body, state, author | The pull request as it was on the host, with the author pseudonymized |
created_at, merged_at, closed_at, base, head | Dates and branch names |
commits | { subject, authored_at, author, sha }, where sha is the commit in this history |
reviews | { by, verdict, body, at }; verdict is approved, changes_requested, or commented |
review_comments | { by, path, line, diff_hunk, body, at }: each inline comment with the file, line, and hunk it was left on |
comments | { by, body, at }: the discussion |
resolved | true when the pull request maps to commits in this history |
base_sha | The state immediately before the change |
after_sha | The state immediately after: the merge commit for a merge, the squash commit for a squash |
head_sha, merge_sha, merge_kind | The pull request branch tip, the landing commit, and whether it landed as a merge or a squash |
patch_stat, files_changed | The size and file list of base_sha..after_sha |
The gold patch for a resolved pull request is git diff <base_sha> <after_sha>: exactly what it landed on its target branch. With title and body as the problem statement and the reviews as feedback, each resolved pull request is a complete before-and-after pair with the review that shaped it. Pull requests with resolved: false came from branches whose commits are not in the history; their discussion is still included.
pull_requests.github.json carries the same record in the shape of GitHub’s /pulls API, for tooling written against a GitHub sync. Every SHA in both files belongs to this repository. The history was rewritten during cleaning, so the host’s original SHAs do not exist here.
The data card
DATA_CARD.md gives the facts a lab screens a codebase on, taken from stored measurements. It never carries a grade or a real name, and it says “not run” or “not recorded” where there is no number.
| Section | What it states |
|---|---|
| Code | Languages, domain and type, stack and notable dependencies, lines of code and files on the default branch, source and history tokens, and whether the tests ran and passed |
| History | Contributors (the count stops at 10), commits across branches and tags, the history span, pull requests and how many rebuild as before-and-after tasks, and review counts |
| Provenance | The signed, non-exclusive license, the exposure check and its date, and any commits pre.dev wrote |
| What anonymisation removed | The cleaning version and date, how many secret values and identities were replaced, the file categories removed from every commit, and that commit hashes differ from the original repository |
The catalog sheet
The catalog sheet has one row per repository, keyed by its catalog ID. Every column comes from one allowlist, and a guard refuses to write a file whose headers or cells carry a real name, an email address, or a grade.
| Column | Meaning |
|---|---|
| Repo ID | The catalog ID |
| Primary Language, Language Breakdown | The language with the most files, and the file count per language |
| Project Type, Industry / Domain, Short Description, Comprehensive Description | What the software is and does, written without owner, client, or product names |
| Lines of Code, Total Files | Lines and files on the default branch, excluding dependencies, build output, and binaries |
| Test Files, Has Automated Tests | Files whose path contains test, spec, or __tests__, and whether there is at least one |
| Core Contributors, Contributors (capped at 10) | Contributors with significant commits, and distinct commit authors counted up to 10 |
| Total Commits, Merge Commits, Remote Branches, Tags / Releases | Counts across all branches and tags |
| Pull Requests, PR Reviews | Pull requests in the delivered record, and their reviews |
| First Commit Date, Last Commit Date, History Span (years) | The dates of the first and last commits, and the years between them |
| Git History Completeness | Complete, or Possibly squashed - low commit count at 10 commits or fewer |
| Source Tokens, Git History Tokens, Total Tokens | See pricing |
| Estimated Value (USD) | Source and history tokens at the rates for your engagement, when rates are set |
| Tooling, External Dependencies | Build, CI, and container tooling found in the tree, and declared dependencies, with names that identify the owner removed |
How the history is cleaned
Cleaning runs before the code is counted, graded, or delivered, and everything after it reads only the cleaned history.
- Secrets. Three secret scanners read every version of every file. Each secret is replaced everywhere in the history with a same-length decoy that was never a live credential.
- Personal data. Email addresses, formatted phone numbers, and profile URLs are replaced. Data files dense with personal records are removed from the history.
- Identities. Every human author, committer, and tagger becomes
Contributor N, consistently in the history and the pull request record. Reviewers who never committed appear asReviewer N. Bot accounts keep their names. - Origin. The origin organization’s name and domains are rewritten in commit messages, file contents, and the pull request record.
- Non-source files. Compiled binaries, archives, vendored dependencies, IDE and editor files, build output, and bulk data files are stripped from the history.
- Verification. Every file version in the rewritten history is searched byte for byte for every original secret value, and every identity must be a pseudonym or a bot. Any residue fails the run, and nothing is stored.
Replacement values are recognizable. Email addresses carry a synthetic top-level domain, phone numbers use the fictional 555 01 block, profile URLs move to the reserved lnkd.example host, and secret-shaped strings are format-preserving decoys. A scanner that flags one of these is flagging a decoy, not a leak.
Delivery checks
A zip is built only if every check passes on the exact bytes it contains:
- The repository was cleaned by the current version of the cleaning pipeline.
- Every branch and tag is present at the same commit, and the repository passes
git fsck. - The pull request record is complete, compared pull request by pull request with the capture from the host.
- The record carries no real email addresses and no author that is not a pseudonym or a bot, and its commit authors match the history’s.
- The zipped files and the record are scanned again for email addresses, phone numbers, and profile URLs.
Pricing
A codebase is priced per token of source code and per token of history. Each has its own rate, set per engagement.
- Source tokens count the current version of every counted file.
- History tokens count every other version of those files, across all branches and tags.
- A token is four bytes of counted file content.
- Code counts in full. Markup, configuration, documentation, and data formats count up to ten times the code beside them, separately for source and for history.
- Dependency directories, build output, and data dumps do not count, and no single file path adds more than 100 MB of history.
Delivery and re-delivery
A delivery comes as a batch of sheets that name repositories by catalog ID only: links.csv with a download link per zip, metadata.csv with the catalog columns, listings.csv with titles, descriptions, and prices, manifest.csv with each zip’s counts, checks.csv with the result of every delivery check, and a README.md. Download links are issued only after your license agreement is confirmed. They expire after seven days, and fresh links can be issued for the same files.
Before links go out, every repository in the batch goes through the exposure check again. A repository found public, archived, forked, or published is held out of the sheets and links. So is a duplicate: the same code twice in one batch, or code already delivered to you. A hold is released only with a recorded reason.
A zip is rebuilt when the cleaning pipeline, the zip format, the stored repository, or its pull request record changes. A rebuilt zip keeps its name and download location, so a link already sent keeps working. When the cleaning itself changed, the rewritten history can carry different commit SHAs; the pull request record is always resolved against the history in the same zip.
Some repositories also have an upgraded copy: the original history plus separate commits that add scaffolding such as documentation, CI, containerization, and tests. Existing source is not changed. The upgraded copy ships as its own zip, with an -upgraded suffix, and its commits come from one more pseudonymous author.