For AI labs
RL Tasks
What a delivered RL task contains: the Harbor task, task.toml, the reward, the QC checks, the difficulty bands, and the delivery archive.
Each RL task is one real change from a private production codebase, rebuilt as a Harbor task that grades offline with a continuous reward. This page describes what a delivered task contains and how its numbers are produced.
How a task is made
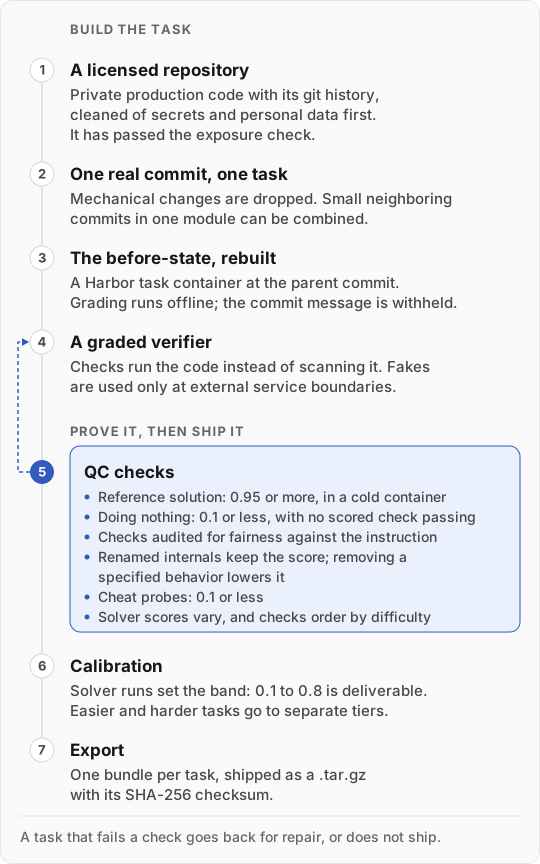
- A licensed repository. Private production code with its git history, cleaned of secrets and personal data before the pipeline reads it. It has passed the exposure check.
- One real commit becomes one task. Mechanical changes are dropped. Small neighboring commits in the same module can be combined into one task.
- The before-state is rebuilt as a Harbor task container at the parent commit. The solver’s workspace carries no git history, grading runs offline, and the original commit message is withheld.
- A graded verifier is written. Checks run the code instead of scanning it. Fakes are used only at external service boundaries.
- QC checks prove the task can be solved and resists gaming. See QC checks.
- Calibration. Solver runs place the task in a difficulty band.
- Export. The task ships as one bundle. A task that fails a QC check goes back for repair, or does not ship.
Bundle layout
<task>/
├── env/                    the Harbor task
│   ├── task.toml
│   ├── instruction.md      what the solver reads
│   ├── environment/        Dockerfile and build context; repo/ is the before-state
│   ├── tests/              the graded suite; test.sh is the verifier entrypoint
│   ├── solution/           solve.sh and canonical.patch: the reference solution
│   └── cheat/solve.sh      known reward-forgery attempts, for you to run
├── manifest.json           task metadata, verifier summary, calibration, file tree
├── qc-report.md            calibration table, mutation results, baselines
├── reproduction-kit.md     the Harbor commands behind every number
├── README.md               a table of the bundle's contents
├── qa-evidence/            reference, do-nothing, mutation, and cheat-probe runs
├── trajectories/           solver runs: trajectory.json, recording.cast, reward.txt
└── traces.jsonl            the same runs as chat-format rows
The container’s workspace is /app. The solver runs as the unprivileged node user. The verifier wipes and restores its own test directory before every grade, so nothing the solver leaves behind can stand in for the graded suite.
task.toml
schema_version = "1.1"

[task]
name = "predev-rl/t-<12 hex>"
description = "<task title>"
authors = []
keywords = []

[metadata]
author_name = "predev-rl-pipeline"
author_email = "rl@pre.dev"
difficulty = "medium"
category = "programming"
tags = ["<task type>", "<stack>", "commit-<8 hex>", "tier:medium"]
sweep_model = "<calibration solver>"
sweep_mean = 0.52
sweep_pass_at_1 = 0.0
commit_message = "" # withheld
before_sha = "<40 hex>"
after_sha = "<40 hex>"

[verifier]
timeout_sec = 1800.0

[agent]
user = "node"

[environment]
build_timeout_sec = 2400.0
cpus = 2
memory_mb = 4096
storage_mb = 20480
gpus = 0
allow_internet = false
mcp_servers = []

[verifier.env]
PD_GRADE_WALL_CAP_SEC = "900"

[environment.env]

[solution.env]| Field | Meaning |
|---|---|
task.name | predev-rl/ plus an opaque task ID. Harbor requires the org/name form. |
task.description | The task title, up to 200 characters. |
metadata.difficulty | medium for the deliverable band; easy or hard for the separate tiers. |
metadata.tags | The task type, up to three stack tags, commit-<8 hex>, and tier:<difficulty>. |
metadata.sweep_model, sweep_mean, sweep_pass_at_1 | The calibration solver, its mean reward, and the share of its runs that scored 0.95 or more. |
metadata.tier_reason | Easy and hard tiers only: why the task left the deliverable band. |
metadata.commit_message | Always empty. The original message would give away the answer. |
metadata.before_sha, after_sha | The commits before and after the change. |
verifier.timeout_sec | The verifier’s wall clock. |
verifier.env.PD_GRADE_WALL_CAP_SEC | The cap on one grading pass: half the verifier timeout. |
agent.user | The solver runs as node. No agent time limit is set; add agent.timeout_sec to impose one. |
environment.* | Resources: 2 CPUs, 4,096 MB of memory, 20,480 MB of storage, no GPU, and 2,400 seconds to build the image. |
environment.allow_internet | false. The image builds with network access; the container then runs and grades without it. |
Reward
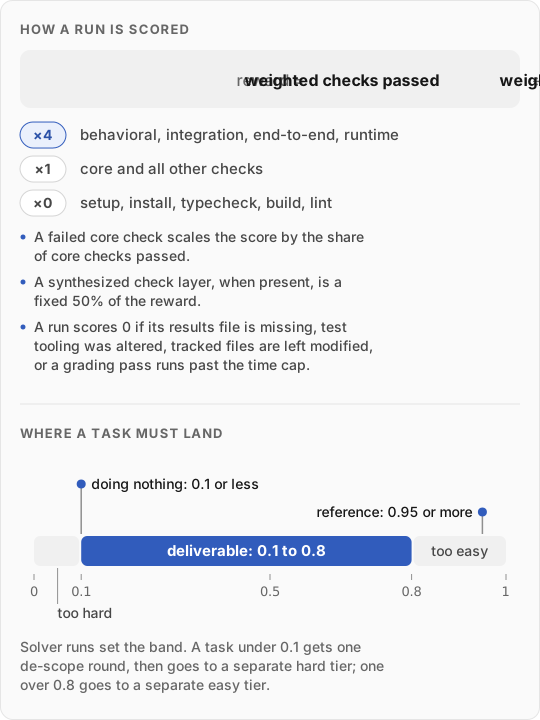
The reward is continuous from 0 to 1:
reward = weighted checks passed / weighted checks total| Check layer | Weight |
|---|---|
| behavioral, integration, end-to-end, runtime | 4 |
| core, and every other layer | 1 |
| setup, install, dependencies, typecheck, build, compile, lint | 0: reported, never scored |
- Core checks gate partial credit. Core checks are the few that prove the task was genuinely attempted. If any fails, the whole score is multiplied by the fraction of core checks that passed.
- Synthesized checks carry a fixed share. Some tasks carry an added synthesized check layer. When it is present it is 50% of the reward, and the other layers make up the rest.
- The verifier writes the reward to
/logs/verifier/reward.txt. It reads results only from a private results file the solver cannot reach. Printed output is never scored.
A run scores 0 when:
- the results file is missing or empty;
- the verifier’s test tooling does not match its SHA-256 manifest;
- the verifier leaves tracked files modified;
- one grading pass runs past
PD_GRADE_WALL_CAP_SEC.
QC checks
Every shipped task clears these checks:
- The reference solution scores at least 0.95, run in a cold container.
- Doing nothing scores at most 0.1, and no scored check passes on the untouched code.
- The checks are audited for fairness against the instruction.
- Mutation checks: renaming internal variables keeps the score at 0.95 or above, and removing one specified behavior lowers it.
- Cheat probes score 0.1 or less: the reference solution changed to exit as soon as it loads, with and without printing forged test results.
- Solver scores vary across runs, and the checks order solver attempts consistently by difficulty (Loevinger H of at least 0.40). Flat or incoherent tasks go back for repair.
- Solver runs place the task in the deliverable band.
qa-evidence/ holds the reference, do-nothing, mutation, and cheat-probe runs. qc-report.md summarizes the baselines, the mutation results, and the calibration table.
Difficulty bands
Solver runs set each task’s band from its solver score:
| Solver score | Band | What happens |
|---|---|---|
| Under 0.1 | Too hard | One de-scope round. If it is still too hard, it moves to a separate hard tier. |
| 0.1 to 0.8, including 0.8 | Deliverable | The task counts as a task. |
| Over 0.8 | Too easy | It moves to a separate easy tier. |
Only deliverable-band tasks count as tasks. A task whose solver runs score no better than doing nothing is treated as ungradeable, not hard, and goes back for repair. Frontier-model results from several model families can be run for a delivered set on request.
Checking overlap with your corpus
manifest.json carries a file_tree for the repository at the before-state, the code the solver starts from:
{
  "file_tree": {
    "algorithm": "sha256",
    "path": "env/environment/repo",
    "file_count": 2,
    "root": "<sha256 of the tree>",
    "files": {
      "package.json": "<sha256 of the file>",
      "src/app.ts": "<sha256 of the file>"
    }
  }
}filesmaps every regular file to the SHA-256 of its contents. Paths are relative to the repository,/-separated, and Unicode NFC..gitand symbolic links are skipped.rootis the SHA-256 of the lines<path>\0<sha256>\n, one per file, sorted by the UTF-8 bytes of the path. The same paths and contents always give the same root.
To check overlap, hash the files in your corpus with SHA-256 and intersect the digests with the values of files. To compare a whole tree, compute its root the same way:
import hashlib, os, unicodedata

def file_tree(root):
    files = []
    for dirpath, dirnames, filenames in os.walk(root):
        dirnames[:] = [d for d in dirnames if d != ".git"]
        for name in filenames:
            full = os.path.join(dirpath, name)
            if name == ".git" or os.path.islink(full) or not os.path.isfile(full):
                continue
            rel = os.path.relpath(full, root).replace(os.sep, "/")
            with open(full, "rb") as f:
                files.append((unicodedata.normalize("NFC", rel), hashlib.sha256(f.read()).hexdigest()))
    files.sort(key=lambda entry: entry[0].encode("utf-8"))
    tree = hashlib.sha256()
    for path, digest in files:
        tree.update(f"{path}\0{digest}\n".encode("utf-8"))
    return tree.hexdigest(), dict(files)
Delivery
Each task ships as a .tar.gz archive with its SHA-256 checksum. Check the archive before you unpack it, then run the reference solution to confirm the verifier in your own environment:
shasum -a 256 <task>.tar.gz
tar -xzf <task>.tar.gz
harbor run -a oracle -p <task>/env
reproduction-kit.md lists the commands behind every number in the bundle, including model runs and the mutation checks. To run the cheat script, put cheat/solve.sh in place of solution/solve.sh in a copy of the task and run the oracle agent.